Distributed Tracing, Done Properly
Following a single request as it passes through several services, queues and databases.
 Marcus Adeyemi

Where most projects go wrong
The usual mistakes:
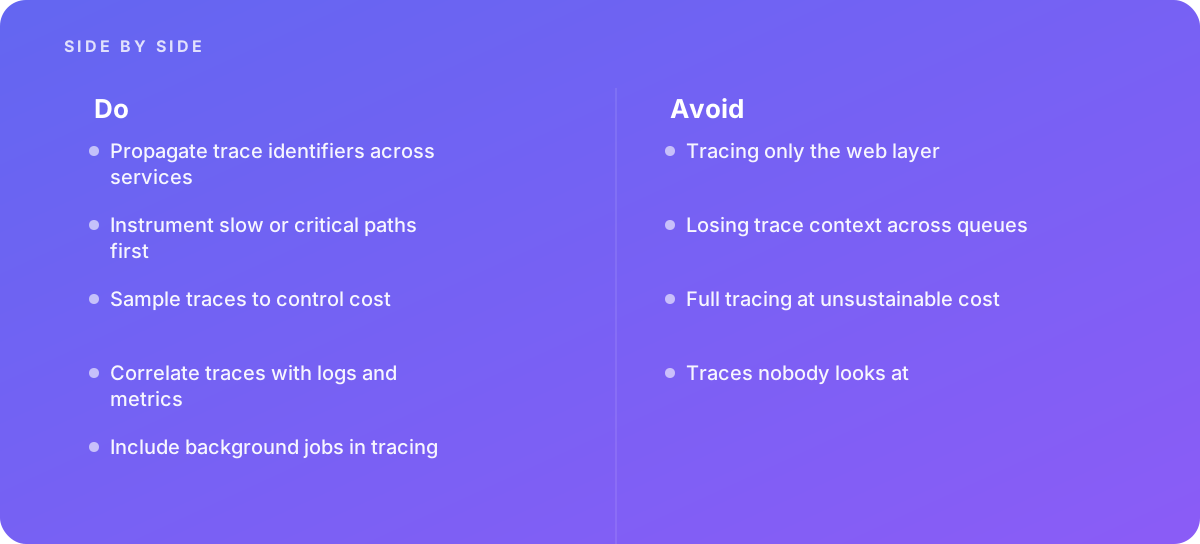
- Tracing only the web layer
- Losing trace context across queues
- Full tracing at unsustainable cost
- Traces nobody looks at
What good looks like instead
- Propagate trace identifiers across services
- Instrument slow or critical paths first
- Sample traces to control cost
- Correlate traces with logs and metrics
- Include background jobs in tracing
Why it matters
In systems with more than one service, logs alone cannot explain where time went or where a request failed.
The specs that matter
| Measure | Figure |
|---|---|
| Trace context | a shared identifier links spans across services |
| Spans | represent units of work within a trace |
| Sampling | high-volume systems trace a subset of requests |
| Standards | trace context propagation is standardized |
Knowing when to hand it over
Tip: Bring in help when performance problems span services.
Where this comes from
- W3C — Trace Context
- Microsoft Learn — Distributed tracing
The figures and practices above come from the sources listed.
Working on something like this?
We take on Web Design & Development work for teams who want it done once, properly. Tell us what you are building and we will tell you honestly whether we are the right studio for it. Start a project.
Where to go next
Spotted something wrong? Report an error on this page. We correct on the page and say what changed.